Rethinking the Function of PPO in RLHF – The Berkeley Synthetic Intelligence Analysis Weblog
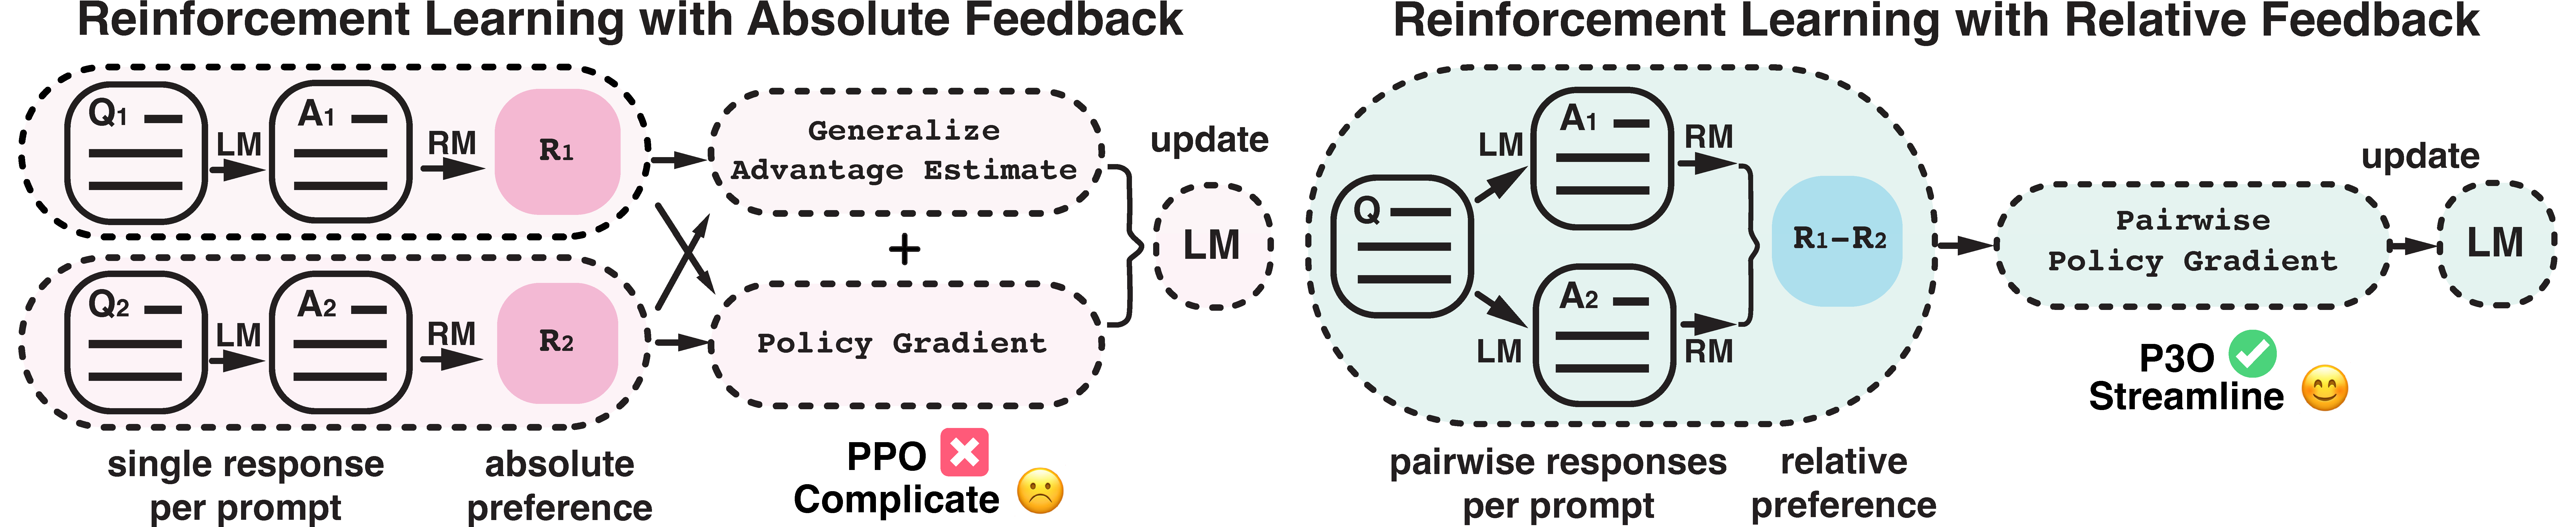
Rethinking the Function of PPO in RLHF TL;DR: In RLHF, there’s stress between the reward studying part, which
Read article →
How Veriff decreased deployment time by 80% utilizing Amazon SageMaker multi-model endpoints
Veriff is an identification verification platform accomplice for modern growth-driven organizations, together with…
Read article →
Panasonic: Full-display meter put in for Mazda Motor Company’s CX-90
Full-display meters from Panasonic Automotive Methods Co., Ltd. are put in in Mazda Motor Company’s (Mazda) CX-90…
Read article →
New cyber algorithm shuts down malicious robotic assault
Australian researchers have designed an algorithm that may intercept a man-in-the-middle (MitM) cyberattack on an…
Read article →
Reinforce Information, Multiply Influence: Improved Mannequin Accuracy and Robustness with Dataset Reinforcement
We suggest Dataset Reinforcement, a technique to enhance a dataset as soon as such that the accuracy of
Read article →
Interpersonal Communication | A Fast Information
Introduction In a world buzzing with digital interactions, the artwork of face-to-face communication typically takes a…
Read article →
Google AI Introduces SANPO: A Multi-Attribute Video Dataset for Out of doors Human Selfish Scene Understanding
For duties like self-driving, the AI mannequin should perceive not solely the 3D construction of the roads and
Read article →
Is AI within the eye of the beholder?
Somebody’s prior beliefs about a man-made intelligence agent, like a chatbot, have a major impact on their interactions
Read article →